PLC Fault Diagnosis That Reduces Production Downtime
A production line stops, the HMI shows a generic fault, and operators are waiting for a reset that will not hold. Effective PLC fault diagnosis starts by resisting the urge to force outputs, clear alarms blindly, or edit logic under pressure. The fastest path back to production is a disciplined method that separates the initiating fault from the downstream conditions it creates.
Thank you for reading this post, don't forget to subscribe!A PLC is often blamed because it is where the fault becomes visible. In many cases, however, the controller is correctly reporting a problem that originated in a field device, safety circuit, power supply, network segment, mechanical process, or permissive condition. Finding that distinction quickly protects uptime, equipment, and personnel.
What PLC Fault Diagnosis Must Determine
The goal is not simply to make the machine run. A sound diagnosis must establish what stopped the process, whether the condition is real, whether the control response was correct, and what must change to prevent recurrence. That requires visibility into the complete control path: inputs, logic execution, outputs, communication, alarms, safety functions, and the physical equipment being controlled.
For example, a motor may fail to start because the PLC output is off. That does not automatically indicate a PLC issue. The output may be intentionally inhibited by an overload contact, a low-pressure permissive, an unacknowledged safety demand, a networked drive fault, or an operating-mode selection. Conversely, if all permissives are valid but the output command never transitions, the fault may be in logic, tag mapping, sequencing, or HMI command handling.
This distinction matters most in high-throughput environments. Replacing hardware without confirming the failure mode can extend downtime, introduce configuration errors, and obscure the underlying cause. A structured approach gives maintenance and controls teams evidence before action.
A Practical PLC Fault Diagnosis Workflow
The sequence should follow the process of elimination while preserving safety and diagnostic evidence. The exact tools vary by platform, but the engineering discipline is consistent across controller families.
Stabilize the equipment before troubleshooting
First, place the process in a known safe condition. Follow lockout/tagout requirements where hazardous energy is present, and do not defeat guards, bypass safety inputs, or force safety outputs to restore production. A safety PLC trip, emergency-stop circuit fault, or safety relay indication requires a defined validation process, not a temporary jumper.
Record the faulted state before cycling power or resetting the controller. Capture HMI alarms, PLC diagnostic buffers, drive fault codes, SCADA trends, network switch status, and operator observations. A power cycle can remove evidence that identifies an intermittent power-quality issue, communication loss, or sequence timing problem.
Confirm controller health and power quality
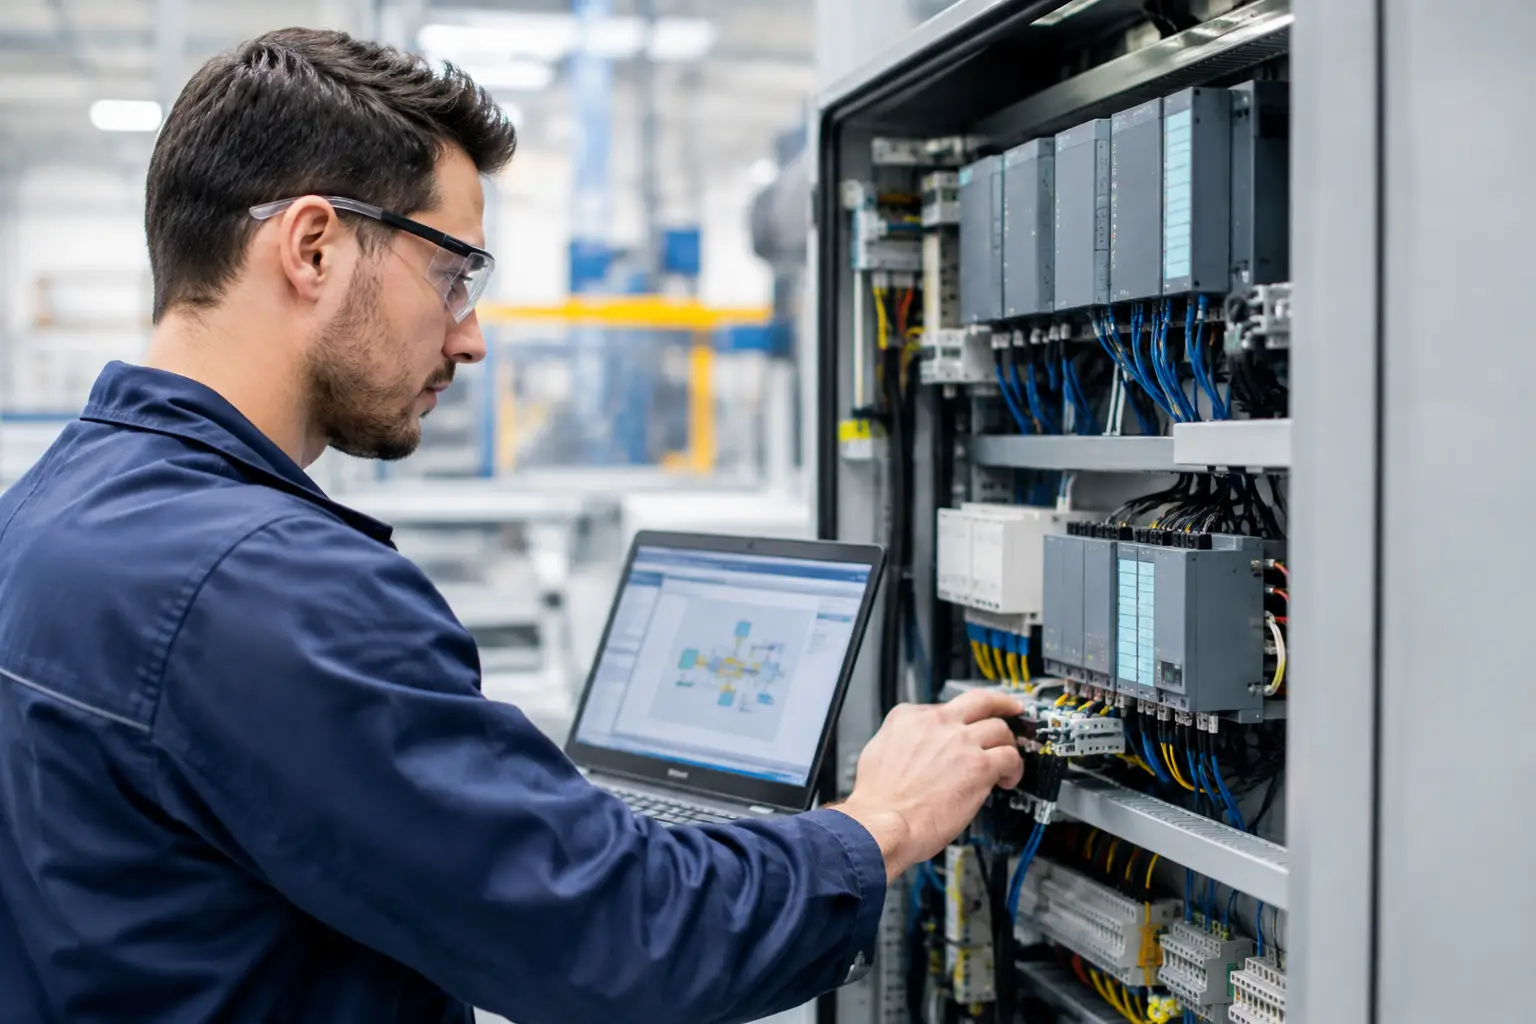
Check the PLC status indicators and programming software diagnostics. Determine whether the CPU is in Run, Program, Remote Program, Fault, or Stop mode. Review major and minor fault records, watchdog events, battery status, memory utilization, module faults, and rack communication status.
Do not stop at a green CPU indicator. Verify the power supply voltage under load, grounding integrity, cabinet temperature, and signs of loose terminals or damaged components. Brownouts and voltage transients can create symptoms that resemble logic failures, particularly where drives, contactors, heaters, and control power share poorly managed electrical infrastructure.
Trace the problem from the physical signal to the logic
Use the controller’s online monitoring tools to follow the signal path. If a photoeye should be made, verify the sensor’s power, alignment, target condition, output LED, field voltage, input terminal, and PLC input bit. If the bit is absent at the controller, the issue is upstream of the program. If the input is present but the sequence does not advance, examine the relevant logic conditions and timers.
This same method applies to analog and networked devices. For an analog transmitter, compare the physical process value with the transmitter display, measured loop signal, input module raw count, scaled engineering value, alarm threshold, and control action. For Ethernet/IP, Profinet, Modbus TCP, or other industrial networks, confirm device connections, status codes, packet loss, duplicate addresses, managed-switch diagnostics, and controller connection limits.
Identify the first-out condition
Complex equipment often produces alarm floods. A single loss of air pressure can trigger cylinder faults, motion timeouts, drive interlocks, and sequence failures. Treating every resulting alarm as an independent failure wastes time.
Look for the first event in the alarm and trend history, then trace its causal path. Well-designed systems use first-out indication, alarm shelving rules, and clear fault hierarchy to distinguish the initiating event from consequential alarms. Where that information does not exist, a controls review can identify opportunities to improve alarm management and diagnostic design.
Test outputs only after input and logic conditions are proven
When the program commands an output, confirm that the output module energizes and that the field device receives the expected voltage or signal. Then verify the physical response. A PLC output can be correct while the contactor coil is open, a solenoid valve is mechanically stuck, a VFD has a local fault, or a pneumatic actuator lacks air supply.
Forcing an output may be appropriate during a controlled commissioning test, but it is not a general troubleshooting shortcut. Forces can bypass sequence protections, mask failed inputs, and create unexpected motion. They must be authorized, documented, removed, and verified before returning equipment to service.
Common Failure Patterns in Industrial Controls
Some faults appear repeatedly across manufacturing and process systems. Intermittent field wiring faults are common in high-vibration areas, cable carriers, wet locations, and poorly terminated panels. A signal may look normal during static testing yet fail when a machine moves or a motor load starts.
Aging I/O modules and power supplies also create intermittent issues, but replacement should follow evidence. Check channel diagnostics, compare similar circuits, inspect load current, and validate field wiring before declaring a module failed. Swapping components without configuration control can create a second problem.
Network-related faults deserve the same rigor. Managed switches, remote I/O adapters, drives, barcode readers, and HMIs may all be functioning individually while a damaged cable, excessive broadcast traffic, incorrect topology, or duplicate IP address disrupts the process. Network diagnostics should be part of the standard fault record, not an afterthought.
Logic and sequencing defects are another category. They often emerge after process changes, recipe additions, equipment modifications, or undocumented online edits. Review the active program against the approved backup, inspect change logs, and confirm that offline documentation matches the installed system. If no reliable backup exists, the immediate recovery task should be paired with a modernization and lifecycle plan.
Safety Faults Require a Different Standard
A standard process fault can be diagnosed by confirming the intended operating sequence. A safety-related fault must also preserve the integrity of the risk-reduction function. Safety PLC diagnostics, dual-channel inputs, safety contactors, guard switches, light curtains, emergency stops, and safety network devices require validation against the machine’s safety design and applicable requirements.
Do not treat repeated safety trips as nuisance alarms. A recurring gate-switch discrepancy, emergency-stop circuit fault, or safety feedback mismatch may indicate worn components, misalignment, wiring degradation, poor device selection, or changes to the machine that were never assessed. Resolving the symptom while leaving the safety function uncertain increases operational risk.
For systems governed by functional safety requirements, diagnostic work should be documented with the same discipline used for changes and proof testing. This is particularly relevant where safety instrumented functions, SIL requirements, or performance level calculations support the operating permit, corporate standard, or risk assessment.
Turn Every Fault Into a Reliability Improvement
The best troubleshooting process ends after the machine is stable, not after the alarm disappears. Document the confirmed root cause, affected equipment, corrective action, parts used, program revisions, and validation results. Add the event to maintenance history with enough detail for the next technician to recognize the pattern.
Repeated faults often point to a design issue rather than a maintenance issue. Better HMI diagnostics, device-level fault mapping, SCADA trending, labeled panel wiring, spare I/O capacity, managed network infrastructure, and controlled PLC backups reduce mean time to repair. They also reduce dependence on tribal knowledge during off-shift failures.
SIS Automations approaches PLC troubleshooting as part of the broader control-system lifecycle: restore the process safely, verify the control architecture, and address the conditions that keep downtime from returning. The most valuable fault diagnosis is the one that improves the next startup, not merely the current restart.